Mastering Table Detection and Extraction in Documents
Extracting tables from scanned documents is hard—manual entry or basic OCR often causes errors and slows down workflows.
Quickly learn how to turn documents containing tables, line-by-line data, or other complex structures into data ready to be used in spreadsheets or Excel. Convert unstructured information into organized, actionable data.
Financial and accounting data is often buried in scattered tables within PDF files or images, making it difficult to access and analyze.
Thanks to artificial intelligence and optical character recognition (OCR) technologies, it is now possible to automatically extract and structure this information even when it is not available as selectable text.
This type of automation is part of a broader approach known as intelligent document processing, which combines OCR, AI, and business rules to process documents at scale.
Once extracted, this data can be organized in a way that maximizes its value, enabling cost savings, error detection, and more efficient expense management.
In this article, we explore the main techniques used to detect and extract tables from documents, along with practical tips to help your developers implement these solutions in your projects.


Today, it is possible to extract and structure data from these tables to maximize its use: opportunities for savings, error detection, expense management.
We present the main artificial intelligence techniques used to detect and extract tables from documents, along with practical tips to help your developers implement these solutions in your own projects.
AI Techniques for Table Detection and Extraction
Computer Vision
Computer vision plays a crucial role in table detection. Common methods include the use of Convolutional Neural Networks (CNN) to identify tabular structures in documents. These networks can be trained on labeled datasets to learn how to recognize table borders and cells.
Key Technique: YOLO (You Only Look Once)
- Description: YOLO is an object detection method that divides an image into a grid and simultaneously predicts multiple bounding boxes and class probabilities for these boxes.
- Advantages: Speed and accuracy. YOLO can process images in real-time, which is essential for applications requiring quick analysis of large documents.
Natural Language Processing (NLP)
Once the tables are detected, the next step is their extraction and understanding. NLP techniques are used to interpret the data contained in the tables and to structure it in a usable manner.
Key Technique: Transformer Models (e.g., BERT, GPT)
- Description: Transformer models are used to understand the context of words and phrases in a table, enabling accurate data extraction.
- Advantages: These models can handle complex information and extract semantic and pragmatic relationships between data, making the analysis more relevant and precise.
Combined Methods
Combining computer vision and NLP results in more robust outcomes. At Koncile, we use CNNs to identify table areas, followed by transformer models to structure the content semantically forming the backbone of our OCR data extraction software.
For example, a common approach is to use computer vision to detect tables and then apply NLP techniques to extract and structure the data.
Example of a Combined Approach at Koncile
- Step 1: Table Detection with CNN: Using convolutional neural networks to detect table areas in documents.
- Step 2: Data Extraction with NLP: Using transformer models to extract and structure data from detected tables.
Practical Tips for Implementation
1. Data Preparation
The quality of training data is crucial for AI model performance. Ensure you have a diverse and well-labeled dataset. Include different types of documents and table formats to make your model more robust.
2. Model Selection
- For Table Detection: Choose established CNN models like YOLO or Mask R-CNN.
- For Data Extraction: Use transformer models like BERT or GPT-4, which have proven effective in natural language understanding.
3. Training and Validation
Separate your dataset into training and validation sets. Use cross-validation techniques to evaluate your models' performance and avoid overfitting.
4. Optimization and Deployment
Once your models are trained, optimize them for real-time use by reducing model size or leveraging GPU acceleration. In finance workflows, these tools can support ocr accounting, helping automate ledger reconciliation, tax detection, and expense report processing. This may include compressing models to make them lighter and faster, as well as setting up robust infrastructures to handle real-time demands.
Real life insights on document automation
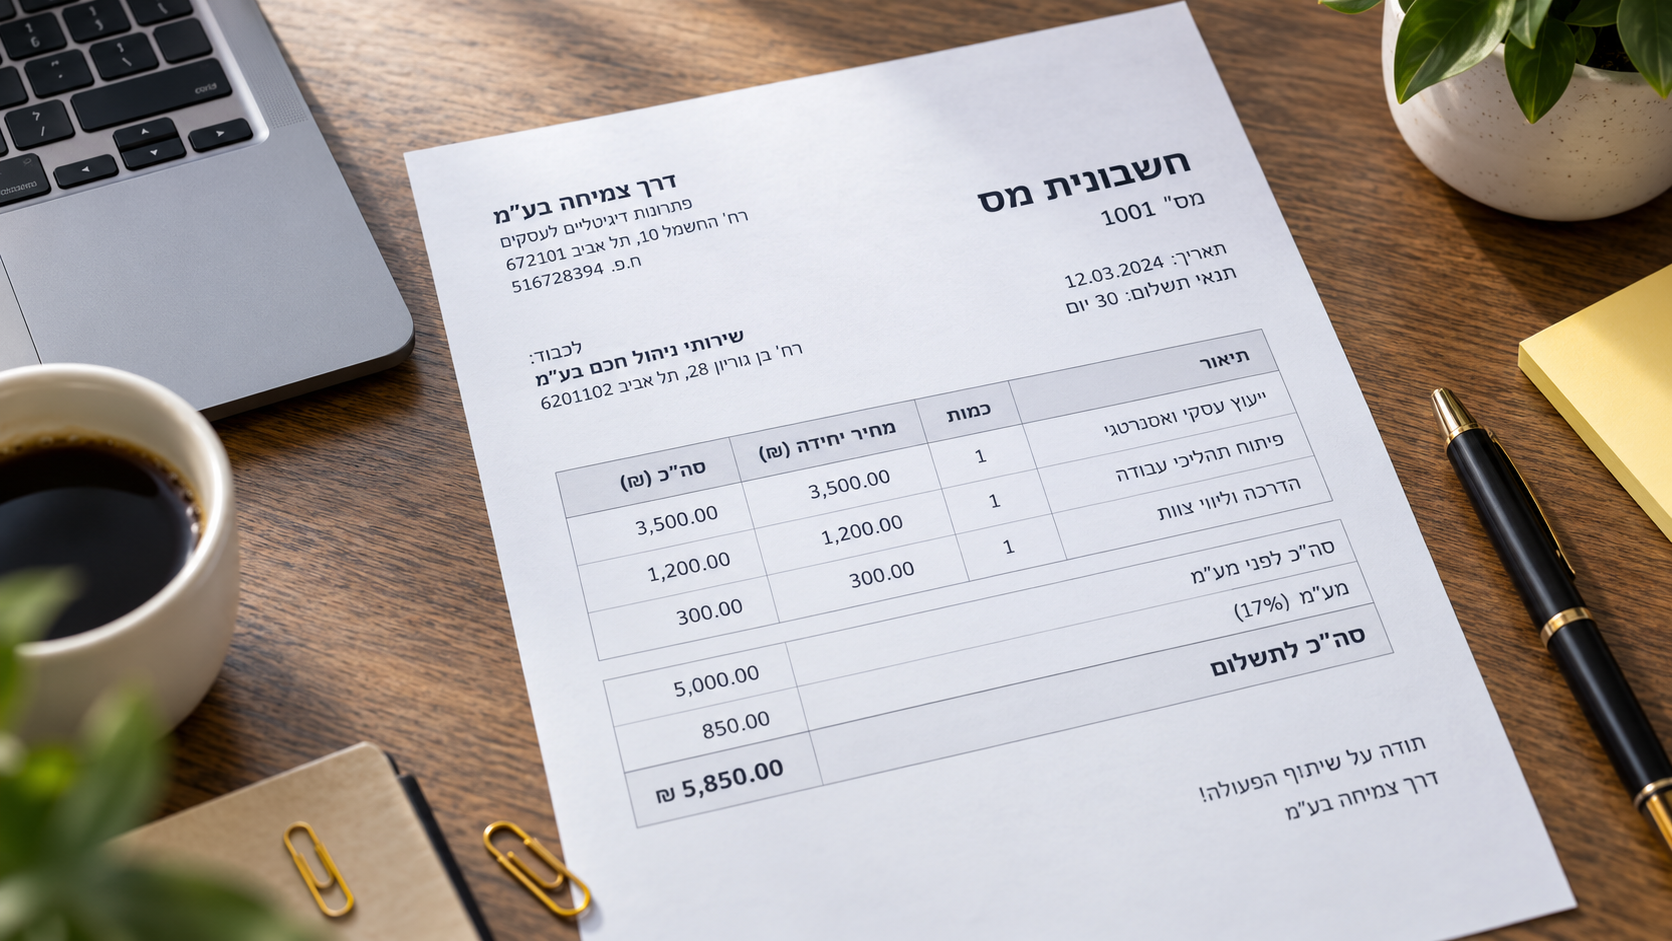
Why Do OCR & Machine Translation Fail Without AI?
Japanese combines three writing systems on one page and should be a hard case for OCR. Benchmark research found the opposite: Japanese accuracy exceeds Latin script. Arabic and Hebrew are where things genuinely go wrong, for specific, documented reasons. Here is what real research shows about why scripts fail differently, and what actually stops the errors before translation compounds them.
How to Detect a Fake Bank Statement: Our 9 Methods
Bank statements are one of the documents most exposed to fraud. At Koncile, we detect up to 1.4% of edited or tampered statements in a set of 150,000 statements. AI generated deepfakes get a lot of attention, but focusing only on them today would be a mistake.
10 Best Open Source OCR Tools in 2026
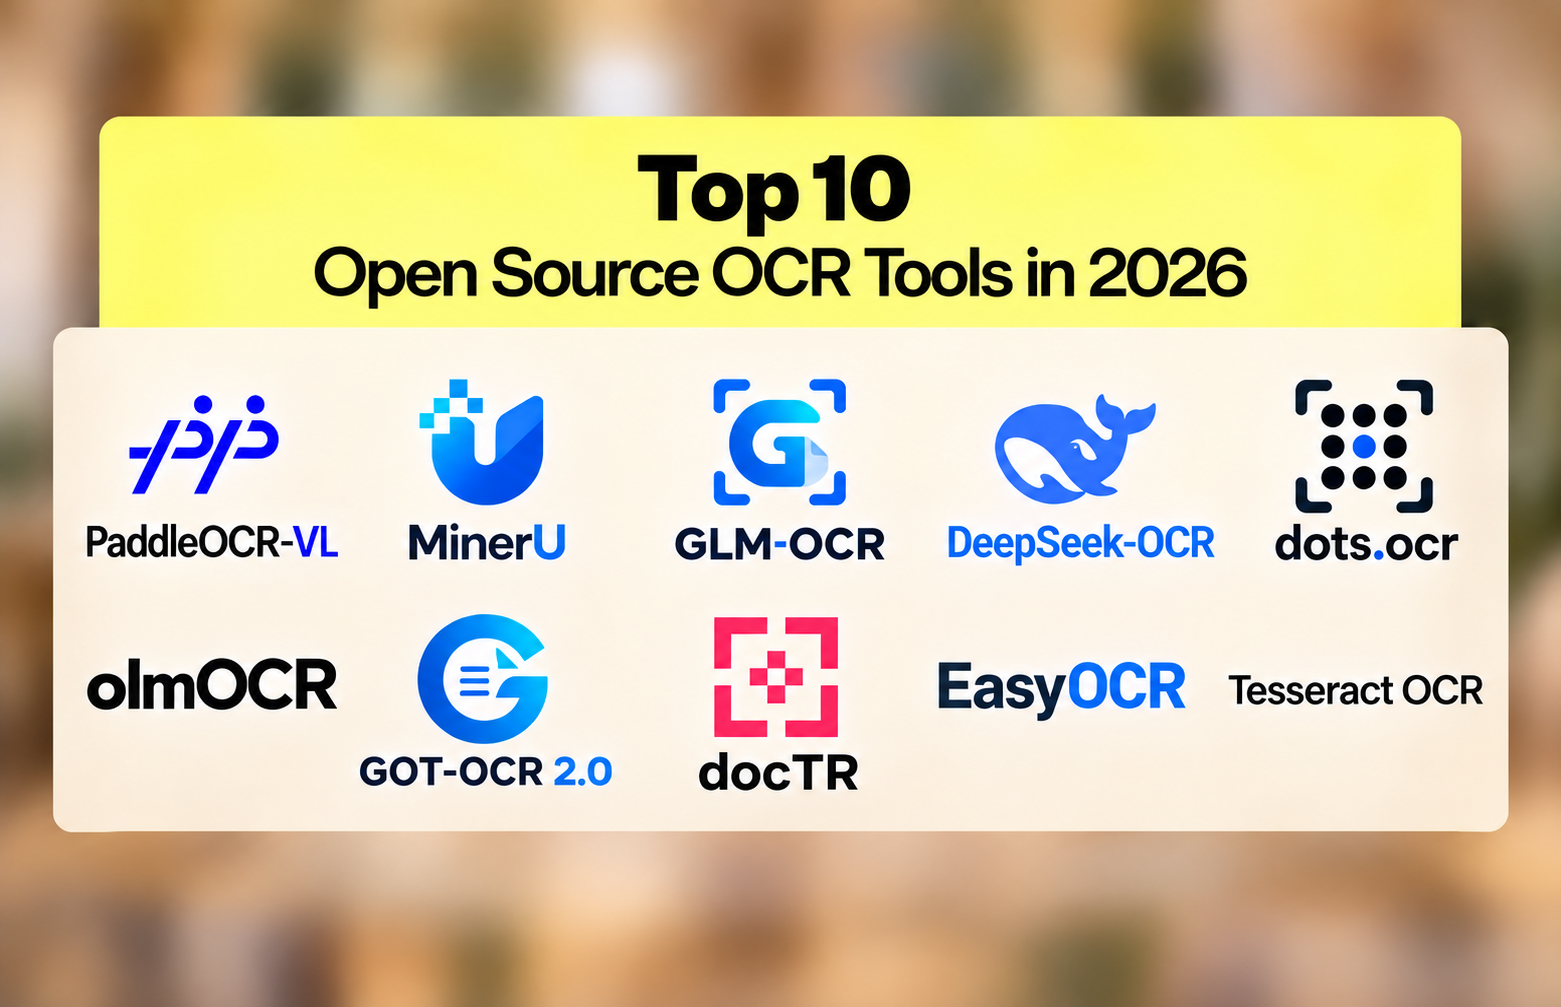
The open source OCR ranking inverted in the past eighteen months. A 0.9-billion-parameter model now reads documents more accurately than a 235-billion-parameter one. PaddleOCR-VL scores 96.34% on OmniDocBench v1.6; Qwen3-VL-235B scores 89.78%. Here are the 10 best open source OCR engines in 2026 and how to pick between them.
Top 10 Document Fraud Detection Software in 2026
Every accuracy figure in this market is self-reported and none has ever been independently verified. Meanwhile forgery services sell documents built specifically to defeat named detection vendors, openly, on the indexed web. Here is our comparison of the 10 best document fraud detection software platforms and the five weaknesses that separate them.